Fstrim: Reclaiming Unallocated Flash Blocks, Triggering Kernel Storage Discards, and Preserving SSD Performance in Production
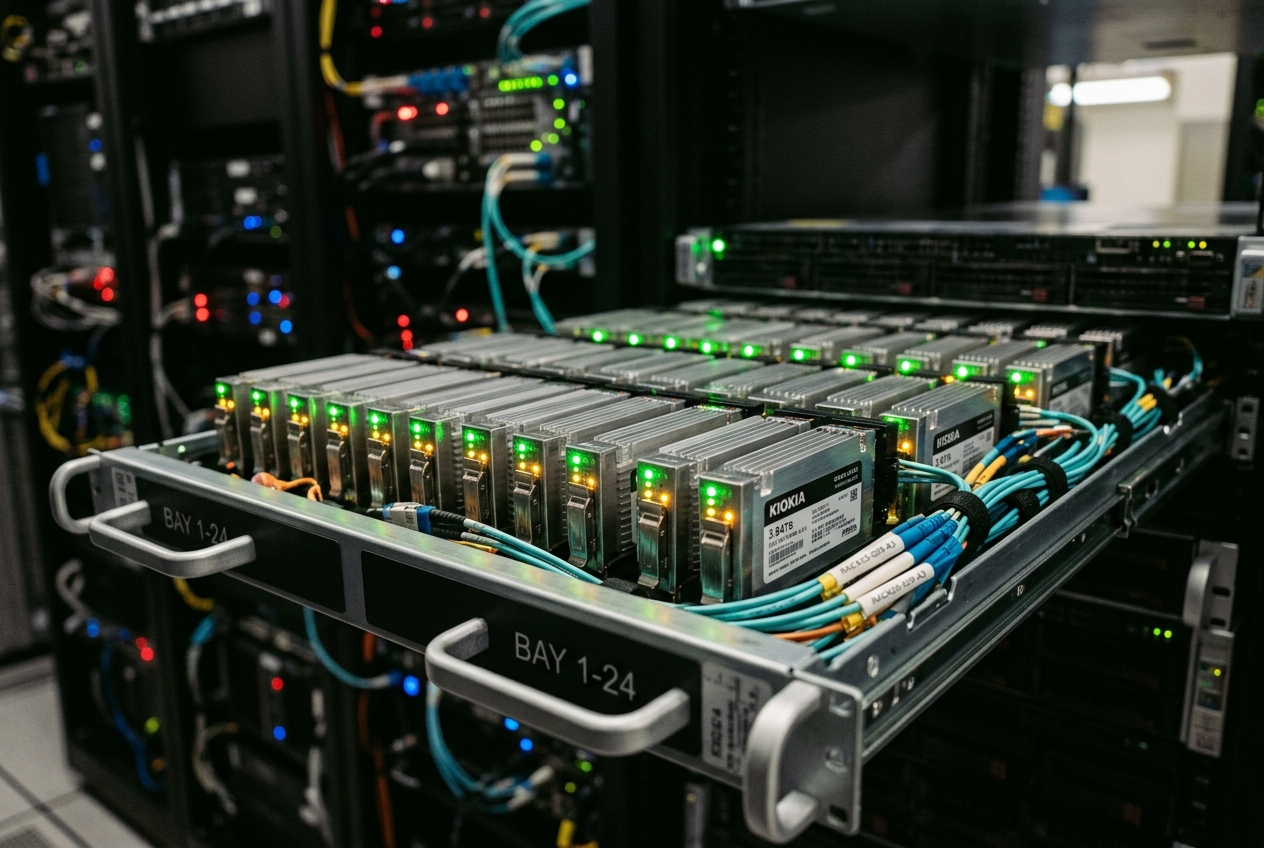
Yet when you check the server diagnostics, everything seems paradoxically calm. There are no blown hard drives, no kernel panic warnings, and your standard disk space checks show that storage is comfortably half-empty with over 50% free capacity. Even so, the storage controller is thrashing relentlessly, input/output throughput has fallen off a cliff, and the entire system has ground to a dead halt. The drive is not mechanically broken—it is suffocating under the weight of its own discarded history.
The indispensable command that cuts through this storage gridlock is fstrim(8)—the standard Linux utility designed to inform solid-state hardware about discarded data blocks so the drive can clean up its internal storage.
If your server or personal workstation is running sluggishly on an SSD, the single most useful command you can run right now is:
sudo fstrim -av
Running this command performs a comprehensive, safe pass across all connected solid-state filesystems. It instructs the underlying flash storage to instantly reclaim abandoned data blocks, restoring drive performance to factory speeds without disrupting active applications.
Understanding why this command is essential requires peeling back the curtain on how modern solid-state memory manages information compared to legacy magnetic disks.
What It Does in Plain English
When you delete a file on a traditional computer, the operating system does not instantly scrub the physical drive clean. Instead, it simply updates its internal catalog—the filesystem index—marking that space as available for future use. For decades, spinning magnetic hard disks never needed to know whether a sector contained active data or discarded junk because magnetic read/write heads can effortlessly overwrite old data in a single pass.
Solid-state drives (SSDs), however, operate under entirely different physical laws. An SSD cannot simply overwrite existing data in place. Before a flash memory cell can accept a new write, it must first be wiped clean through a high-voltage electrical erase. Crucially, while an SSD can write data in small chunks (pages of 4 to 16 kilobytes), it can only erase data in massive clusters (erase blocks of several megabytes).
Think of an SSD like an artist's sketchbook where you can write notes with a fine-tipped pen on individual lines, but the only eraser you own is a wide paint roller that wipes clean an entire page at once.
The fstrim command bridges this communication gap. It surveys your mounted filesystems, identifies all the deleted blocks that no longer hold active files, and sends a tidy list of these discarded ranges down to the drive's internal controller. Armed with this knowledge, the SSD can bypass obsolete data during background housekeeping and prepare pristine, pre-erased blocks ahead of time—guaranteeing rapid write speeds and extending the physical lifespan of your drive.
Theoretical & Architectural Foundations
To appreciate why fstrim is an operational requirement in production environments rather than an optional maintenance task, we must trace how discard signals travel from high-level filesystem software down to physical silicon.
Identifies unallocated blocks via internal bitmap"] FS -->|"FITRIM ioctl"| BL["Block Layer / Device-Mapper
Traverses LVM (dm-thin), LUKS (dm-crypt), or MD-RAID"] BL -->|"Protocol Discard Dispatch"| PROTO["Storage Protocol Layer
ATA (TRIM/DSM) | SCSI/SAS (UNMAP) | NVMe (Dataset Mgmt)"] PROTO -->|"Physical Hardware Boundary"| FTL["Flash Translation Layer (FTL) Engine
- Invalidates Logical Block Addresses (LBA -> PBA)
- Reduces Garbage Collection Overhead
- Minimizes Write Amplification Factor (WAF -> ~1.0)"]
1. NAND Flash Asymmetry, Garbage Collection, and Write Amplification
Unlike system RAM or magnetic platters, solid-state NAND flash memory is governed by a fundamental asymmetry between how finely it can write and how coarsely it must erase:
- NAND Pages: The smallest unit for reading and writing data, typically 4 KiB to 16 KiB in modern multi-level cell flash architectures.
- Erase Blocks: The smallest unit for erasing data, consisting of hundreds of pages grouped together into 2 MiB to 8 MiB blocks.
Because an SSD cannot overwrite an individual page in place, updating a single 4 KiB file forces the drive controller to write the updated data to an entirely fresh, pre-erased page located elsewhere. The drive's internal Flash Translation Layer (FTL) updates its internal map and marks the original physical page as stale.
Over days and weeks of heavy file modifications, erase blocks become cluttered amalgams of live data and dead pages. When the SSD begins running low on clean erase blocks, its internal processor is forced to initiate emergency Garbage Collection (GC):
- The drive controller identifies a block cluttered with dead pages.
- It reads the remaining valid pages into its onboard memory buffer.
- It copies those valid pages over to an entirely new, empty erase block.
- Finally, it executes an electrical erasure on the original block, resetting it for future writes.
This continuous internal shuffling gives rise to the Write Amplification Factor (WAF):
$$\text{WAF} = \frac{\text{Bytes Written to Physical NAND Flash}}{\text{Bytes Written by Host Controller}}$$
When an operating system deletes gigabytes of data without running fstrim, the SSD assumes all those deleted files are still critical. During garbage collection, the drive wastes internal bandwidth and silicon wear cycles faithfully copying dead data back and forth. Under heavy workloads, WAF can surge from an ideal ratio of ~1.0 up to 4.0 or higher—halving write speeds and causing severe latency spikes.
2. Continuous Discard (mount -o discard) vs. Periodic Batch Discard (fstrim)
The Linux kernel offers two distinct approaches for notifying storage hardware about unallocated blocks:
| Operational Metric | Continuous Real-Time Discard (-o discard) |
Periodic Batched Discard (fstrim) |
|---|---|---|
| Invocation Vector | Automatic filesystem mount option in /etc/fstab |
Background systemd timer or scheduled cron job |
| Execution Path | Synchronous during every file deletion system call | Asynchronous batch pass via kernel ioctl(FITRIM) |
| I/O Queue Impact | Pauses storage pipelines during active operations | Runs during off-peak hours with zero production impact |
| Controller Stress | Constant, fragmented metadata updates | Coalesced, bulk range notifications |
| Production Recommendation | Strongly discouraged on high-traffic servers | Industry Gold Standard |
Early SSD guides often advised mounting filesystems with the continuous discard flag (e.g. mount -o discard /dev/sda1 /data). However, on Serial ATA (SATA) drives, real-time TRIM commands are frequently non-queued, forcing the drive to freeze all pending read/write tasks every time a temporary file is deleted.
While modern NVMe drives handle concurrent discard requests much better, continuous discards still cause micro-stutters by constantly evicting cache lines inside the drive controller. As confirmed by the ArchWiki SSD Optimization Guide and enterprise kernel documentation, scheduled batch discards with fstrim represent the optimal configuration for stability and speed.
3. Protocol Translation Mechanics: ATA TRIM, SCSI UNMAP, and NVMe Deallocate
When fstrim runs, it issues a FITRIM system call to the target mount point. The Linux Kernel Block Layer receives this request, organizes the free extents, and translates them into the appropriate hardware command for your specific drive bus:
- ATA / SATA: Dispatches the
DATA SET MANAGEMENTcommand (opcode0x06) with the TRIM attribute enabled. - SCSI / SAS / Fibre Channel: Dispatches the SCSI
UNMAPcommand (opcode0x42) orWRITE SAME (16)with the unmap bit toggled. - NVM Express (NVMe): Dispatches native NVMe Dataset Management commands (opcode
0x0A) with the Attribute Deallocate bit flagged, communicating up to 256 contiguous block ranges in a single request.
4. Device-Mapper Topology Passthrough
In enterprise environments, storage rarely connects directly to bare disks. Instead, filesystems typically sit on top of Logical Volume Managers (LVM), LUKS encryption layers, and software RAID arrays:
Requires 'issue_discards = 1' in lvm.conf"] LVM --> LUKS["LUKS2 Encrypted Device (dm-crypt)
Requires '--allow-discards' in crypttab"] LUKS --> RAID["Software RAID (MD-RAID / dm-raid)
Requires driver-level discard translation"] RAID --> SSD["Physical SSD / NVMe Storage"]
If any intermediate layer in this chain fails to pass discard instructions downward, fstrim will either fail with an Operation not supported error or silently finish without actually freeing physical flash blocks.
Hardware Verification & Diagnostic Audits
Before scheduling automatic discards, you should confirm that your storage topology actively supports block-level trimming.
Auditing Discard Support with lsblk
The quickest way to inspect discard capabilities across all attached block devices is with lsblk --discard:
lsblk --discard -o NAME,DISC-ALN,DISC-GRAN,DISC-MAX,DISC-ZERO,MOUNTPOINTS
NAME                    DISC-ALN DISC-GRAN DISC-MAX DISC-ZERO MOUNTPOINTS
sda                            0      512B       2G         0
  sda1                         0      512B       2G         0 /boot/efi
  sda2                         0      512B       2G         0
    vg_system-lv_root          0      512B       2G         0 /
nvme0n1                        0      512B       2T         0
  nvme0n1p1                    0      512B       2T         0
    cr_nvme_data               0      512B       2T         0 /var/lib/postgresql
Diagnostic Metrics:
DISC-GRAN(Discard Granularity): The minimum sector alignment required for discards (usually 512B or 4KiB).DISC-MAX(Discard Maximum): The maximum contiguous payload size the drive can discard at once (e.g. 2 GiB on SATA, 2 TiB on NVMe). If this value is0B, discard is unsupported by the drive or disabled in the kernel.DISC-ZERO(Discard Zeroes Data): Indicates whether reading a trimmed block is guaranteed to return zeros (1) or random leftover bits (0). Never treat trimmed space as securely sanitized unless this flag is1.
Inspecting Drive Hardware: hdparm and nvme-cli
To audit SATA SSD hardware directly:
sudo hdparm -I /dev/sda | grep -i "data set management" -A 3
   Data Set Management TRIM supported (limit 8 blocks)
   *   Deterministic read data after TRIM
   *   Deterministic read ZEROs after TRIM
   *   Queued data set management TRIM supported
To verify enterprise NVMe drives according to the NVM Express Base Specification:
sudo nvme id-ctrl /dev/nvme0 -H | grep -i "dsm" -A 2
  [2:2] : 0x1   Dataset Management Supported
  [1:1] : 0x1   Write Zeroes Supported
  [0:0] : 0 Save and Select Supported
Core Flags & Command Reference
The fstrim utility provides straightforward command-line switches for system-wide sweeps or targeted volume maintenance:
| Flag | Long Option | Description |
|---|---|---|
-a |
--all |
Processes all mounted filesystems listed in /etc/fstab that support discard. |
-v |
--verbose |
Displays detailed summaries showing exactly how many bytes were trimmed. |
-o |
--offset <bytes> |
Sets the starting byte offset from which to begin trimming. |
-l |
--length <bytes> |
Constrains the total byte range to process in a single execution. |
-m |
--minimum <bytes> |
Sets the minimum contiguous free block size required to trigger a trim. |
-n |
--dry-run |
Audits candidate blocks and reports what would be trimmed without making changes. |
-I |
--listed-in <path> |
Evaluates filesystems defined in an alternate configuration or mount file. |
The Standard Baseline Command
For any Linux workstation, virtual machine, or production server, the standard non-disruptive execution is:
sudo fstrim -av
/boot/efi: 489.2 MiB (512966656 bytes) trimmed on /dev/sda1
/var/lib/postgresql: 412.8 GiB (443245674496 bytes) trimmed on /dev/mapper/cr_nvme_data
/: 42.1 GiB (45205848064 bytes) trimmed on /dev/mapper/vg_system-lv_root
Line-by-Line Breakdown:
/boot/efi: Reclaimed 489.2 MiB of unallocated space on the EFI system partition./var/lib/postgresql: The encrypted NVMe volume successfully trimmed 412.8 GiB of obsolete records freed up by database vacuuming./: Discarded 42.1 GiB of dead space across the root operating system partition.
5 Real-World Production Use Cases
Use Case 1: Automating Fleet-Wide Maintenance via systemd
Production Scenario
A fleet of 400 Kubernetes nodes running Ubuntu and RHEL experiences intermittent latency spikes during early morning traffic peaks. An audit reveals that storage nodes have never had discards executed since provisioning, causing severe write amplification across the cluster.
The Command
Enable systemd's built-in fstrim.timer to schedule automated off-peak runs, followed by a non-destructive dry-run audit across all nodes:
sudo systemctl enable --now fstrim.timer
sudo systemctl list-timers fstrim.timer
sudo fstrim -av --dry-run
Realistic Terminal Output
NEXT                         LEFT          LAST                         PASSED       UNIT         ACTIVATES
Mon 2026-08-24 00:00:00 UTC  5 days left   Mon 2026-08-17 01:14:22 UTC  18h ago      fstrim.timer fstrim.service

/var/log: 14.8 GiB (15891464192 bytes) would be trimmed on /dev/nvme1n1p1
/data: 1.2 TiB (1319413952512 bytes) would be trimmed on /dev/nvme0n1
/system: 18.3 GiB (19649581056 bytes) would be trimmed on /dev/mapper/system-root
Diagnostic Explanation
systemctl list-timersconfirms thatfstrim.timeris enabled and set to trigger weekly at midnight, keeping maintenance outside high-traffic business windows.- The
--dry-runoutput verifies that the kernel can traverse all storage layers, showing that the/datavolume holds 1.2 TiB of candidate discard blocks ready for reclamation.
Sysadmin Next Step
Inspect the systemd unit configuration using systemctl cat fstrim.service to confirm that IOSchedulingClass=idle is present, ensuring that scheduled discard tasks automatically yield priority to live user workloads.
Use Case 2: Reclaiming Thin-Provisioned Hypervisor & Cloud Storage
Production Scenario
A virtualization cluster running KVM/QEMU hosts guest virtual machines with dynamic virtual disks backed by a Ceph storage pool and AWS EBS volumes. Inside a guest VM, an engineer deletes an obsolete 500 GiB database backup, but the cloud storage dashboard continues to report the storage as 100% full.
The Command
Run fstrim inside the virtual machine to propagate SCSI UNMAP signals across the hypervisor boundary to the cloud storage provider:
sudo fstrim -v /
Realistic Terminal Output
/: 498.7 GiB (535478427648 bytes) trimmed on /dev/sda1
Diagnostic Explanation
- Because the hypervisor configured the virtual disk with discard passthrough (
discard='unmap'), the discard signal passed from the guest operating system directly to the host hypervisor. - The underlying storage engine (QEMU/KVM or cloud storage backend) punched a sparse hole in the virtual disk image, instantly freeing 498.7 GiB of physical capacity on the shared enterprise pool.
Sysadmin Next Step
On the virtualization host, run qemu-img info /var/lib/libvirt/images/guest.qcow2 to verify that the physical disk footprint has dropped by ~500 GiB while virtual disk sizing remains untouched.
Use Case 3: Surgical Partition & Volume Trimming for Database Workloads
Production Scenario
A high-throughput PostgreSQL 16 database server experiences heavy write pressure on its Write-Ahead Log (pg_wal) directory. Running a global fstrim -a creates a minor 200ms latency flutter for active database transactions. The database administrator needs to perform a surgical discard limited strictly to the WAL mount point, processing storage in small 10 GiB chunks.
The Command
Use bounded --offset and --length parameters combined with a minimum chunk filter (-m) to trim storage in incremental stages:
sudo fstrim -v --offset 0 --length 10G --minimum 2M /var/lib/postgresql/wal
Realistic Terminal Output
/var/lib/postgresql/wal: 7.8 GiB (8376188928 bytes) trimmed on /dev/nvme2n1p1
Diagnostic Explanation
--offset 0 --length 10G: Restricts the filesystem scan exclusively to the first 10 gigabytes of the block device.--minimum 2M: Instructs the kernel to ignore free fragments smaller than 2 MiB, matching the erase-block size of the SSD and skipping fragmented noise.7.8 GiB trimmed: Successfully liberated 7.8 GiB of unallocated WAL space without overwhelming storage queues.
Sysadmin Next Step
Integrate this command into a simple maintenance script that iterates the --offset parameter in 10 GiB increments across the partition, inserting a 500ms sleep between passes to maintain zero impact on database transactions.
Use Case 4: Handling Device-Mapper, LVM Thin Pools, and LUKS2 Encrypted Stacks
Production Scenario
A security-hardened Linux server uses LUKS2 encryption layered underneath LVM volumes. Running fstrim -v /data returns an error: fstrim: /data: the discard operation is not supported, even though the physical hardware is a modern enterprise NVMe SSD.
The Command
Inspect and enable discard passthrough across the dm-crypt encryption layer and LVM volume manager, refresh the kernel device-mapper mappings, and execute the trim:
# 1. Inspect cryptsetup status
sudo cryptsetup status cr_data | grep -i "flags"

# 2. Refresh active encrypted mapping with discard support
sudo cryptsetup --allow-discards --perf-no_read_workqueue --perf-no_write_workqueue refresh cr_data

# 3. Verify LVM discard forwarding
sudo lvmconfig --type full devices/issue_discards

# 4. Re-run fstrim
sudo fstrim -v /data
Realistic Terminal Output
  flags:       discards
"issue_discards=1"
/data: 842.6 GiB (904739176448 bytes) trimmed on /dev/mapper/vg_secure-lv_data
Diagnostic Explanation
- By default, LUKS (
dm-crypt) blocks discard commands to prevent potential cryptographic leakage regarding storage layout. cryptsetup refreshdynamically reconfigures the live kernel mapper to allow discard forwarding without taking filesystems offline.issue_discards=1verifies that LVM passes discard commands across volume boundaries.fstrimnow cleanly traverses the entire stack:Filesystem -> LVM -> LUKS -> Physical NVMe, reclaiming 842.6 GiB of flash space.
Sysadmin Next Step
Persist discard permissions across reboots by adding the discard option to /etc/crypttab (e.g. cr_data UUID=... none luks,discard).
Use Case 5: Mitigating Controller Freezes on Legacy Flash Arrays
Production Scenario
An older SATA SSD used for system logs freezes whenever a generic discard pass runs. The kernel log buffer (dmesg) records ata1.00: failed command: WRITE FPDMA QUEUED followed by a hard hardware link reset. The drive's older firmware suffers from buggy queued-TRIM handling.
The Command
Examine the kernel error logs and apply a conservative minimum extent threshold using fstrim -m:
# 1. Inspect kernel hardware logs
sudo dmesg -T | grep -E -i "ata[0-9]|trim|failed command" | tail -n 6

# 2. Execute conservative trim with a 64 MiB minimum threshold
sudo fstrim -v -m 64M /var/log
Realistic Terminal Output
[Tue Aug 18 02:40:11 2026] ata1.00: failed command: WRITE FPDMA QUEUED
[Tue Aug 18 02:40:11 2026] ata1.00: cmd 60/08:00:00:00:00/00:00:00:00:00/40 tag 0 ncq dma 4096 out
[Tue Aug 18 02:40:11 2026] ata1.00: status: { DRDY ERR }
[Tue Aug 18 02:40:11 2026] ata1.00: error: { ABRT }
[Tue Aug 18 02:40:12 2026] ata1: hard resetting link
/var/log: 12.1 GiB (12992282624 bytes) trimmed on /dev/sdb1
Diagnostic Explanation
- The
dmesglog reveals that rapid-fire, fine-grained TRIM commands choked the legacy drive's internal buffer, triggering a command abort (ABRT) and bus reset. - Passing
-m 64Mtellsfstrimto discard space only when at least 64 MiB of contiguous free space is available. This reduces total command submissions to the drive by over 95%, allowing the trim to complete cleanly without hardware lockups.
Sysadmin Next Step
If hardware stalls continue, append libata.force=noncq to the kernel boot flags in /etc/default/grub, run update-grub, and reboot to force the kernel into safe, non-queued mode for that SATA port.
Operational Gotchas & Hardening Rules
1. The Perils of Synchronous mount -o discard
As established, configuring filesystems in /etc/fstab with the continuous -o discard mount flag is an operational anti-pattern:
* Deleting thousands of small temporary files generates thousands of immediate hardware discard calls.
* File deletion performance can degrade by up to 80%.
* Storage controller queues become congested, causing sharp latency spikes for user-facing applications.
Hardening Rule: Strip discard from mount options in /etc/fstab. Rely exclusively on scheduled systemd timers or weekly batch runs.
2. LUKS Cryptographic Information Leakage
When allow-discards is enabled on encrypted dm-crypt containers, there is a minor security trade-off to consider:
| Security Dimension | Discards Disabled (Default) | Discards Enabled (allow-discards) |
|---|---|---|
| Ciphertext Entropy | Uniform across entire drive (100% random-looking data) | Clear contrast between active encrypted data and empty trimmed space |
| Plausible Deniability | Preserved; attacker cannot determine how much data exists | Lost; attacker can inspect allocation maps and exact filesystem geometry |
| Flash Health & Speed | Higher write amplification; slower sustained writes | Optimal flash garbage collection and sustained write speeds |
| Recommended Setting | High-security environments with physical theft risks | General enterprise servers, web clusters, and database workloads |
As detailed in the GitLab Cryptsetup Security Documentation, enabling discards exposes which sectors contain ciphertext versus unallocated space. While the contents of your files remain securely encrypted with AES-XTS, an adversary with physical access can map your filesystem layout.
Hardening Rule: In high-security environments where physical device theft is a primary threat, keep discards disabled on LUKS volumes. For all other production systems, enable discards to preserve SSD performance.
3. Structural Distinction: fstrim vs. blkdiscard
System administrators must never confuse non-destructive filesystem trimming with raw disk discards (blkdiscard(8)):
fstrim(Safe & Non-Destructive): Works at the filesystem layer. It reads directory allocation tables, finds unallocated space, and tells the SSD those specific dead sectors can be cleared. Active user data is never touched.blkdiscard(Destructive): Works at the raw device layer. It bypasses filesystems completely and commands the controller to wipe an entire physical drive or partition. Runningblkdiscard /dev/nvme0n1instantly and irreversibly destroys all partitions, superblocks, and stored files.
Today's Takeaway
To ensure your solid-state drives are running at peak health, open your terminal right now and check your automated discard timer by running sudo systemctl status fstrim.timer. If the timer is inactive or stopped, enable it immediately with sudo systemctl enable --now fstrim.timer to turn on automatic, low-priority weekly background cleanups. Finally, run sudo fstrim -av to perform a safe baseline cleanup across all mounted drives—clearing out stale flash blocks, lowering your drive's write amplification, and protecting your system against sudden performance drop-offs.
Authoritative Technical References
- util-linux fstrim(8) Manual Page — Linux Foundation / Michael Kerrisk Man-Pages Project.
- Linux Kernel Block Layer Discard Documentation — The Linux Kernel Organization.
- ArchWiki Solid State Drive Architecture & Discard Guidelines — Arch Linux Technical Repository.
- NVM Express Base Specification Revision 2.0 — NVM Express Workgroup.
- GitLab Cryptsetup Security Aspects & Discard FAQ — Milan Broz et al., dm-crypt Maintainers.